Safety Testing for Student-Facing AI Tutors
Red-team your AI tutor or doubt-solving bot before students use it: unsafe content, jailbreaks, confidently wrong answers, integrity bypasses and leaks of other students' data.
- Capability:
- AI Security & Compliance
- Industry:
- Education & Coaching
Who it is for
- CTO (Edtech)
- Head of Product, Learning Apps
- Trust and Safety Lead
- Academic Quality Head
The problem
Coaching institutes and edtech companies are adding AI tutors that solve doubts from a photo, explain concepts in Hinglish and chat with students late at night. Most users are teenagers under exam pressure. A tutor that can be talked into unsafe content, gives a confidently wrong derivation or reveals another student's data creates a safety incident, not just a bug.
Teenagers test boundaries
Students will try role-play, language switching and persistence to get the tutor to say things it should not.
Confident wrong answers
A wrong physics or chemistry solution explained fluently is worse than no answer, especially the night before an exam.
Integrity bypass
Tutors meant to guide step by step can be pushed into handing over full answers during live tests or graded assignments.
Student data in context
Tutors that read progress records, chat history or uploaded images can leak one student's data to another, or follow instructions hidden in an uploaded image.
What we build
We run a structured red-team of your tutor through the channels students use: app chat, image upload and voice mode where you offer it. Multi-turn playbooks in English, Hindi and Hinglish probe age-inappropriate content, handling of self-harm and distress, jailbreaks through role-play, academic-integrity bypasses, prompt injection hidden in uploaded question images, retrieval of other students' records and system-prompt extraction. A solution-accuracy set checks answers against faculty-verified solutions. Each test is scored PASS, RISK or FAIL with the full transcript as evidence, then reviewed by our security lead and your academic or safety reviewer. You get prioritised fixes and a re-test.
- Multi-turn adversarial playbooks in English, Hindi and Hinglish, by text and voice
- Child-safety checks for unsafe content, distress handling and escalation to humans
- Academic-integrity tests against exam-mode and assignment-mode policies
- Indirect prompt injection through uploaded images, PDFs and question text
- Cross-student data leakage and access-control tests on tutor memory and records
- Solution-accuracy benchmark against faculty-verified answers for each subject
How it works
- 01Scope and policiesWe agree the tutor's channels, age bands, content policy, integrity rules and the data it can access.
- 02Build playbooksAttack and accuracy scenarios are written for your subjects, languages and student personas.
- 03Run testsPlaybooks run against a staging tutor, automated and by hand, across chat, image upload and voice.
- 04Score resultsEach conversation is scored PASS, RISK or FAIL by rules and an evaluator model.
- 05Human reviewOur security lead and your academic or safety reviewer confirm every RISK and FAIL.
- 06Report and re-testYou receive evidence, mapped risks and fixes, and we re-run the failed tests after changes.

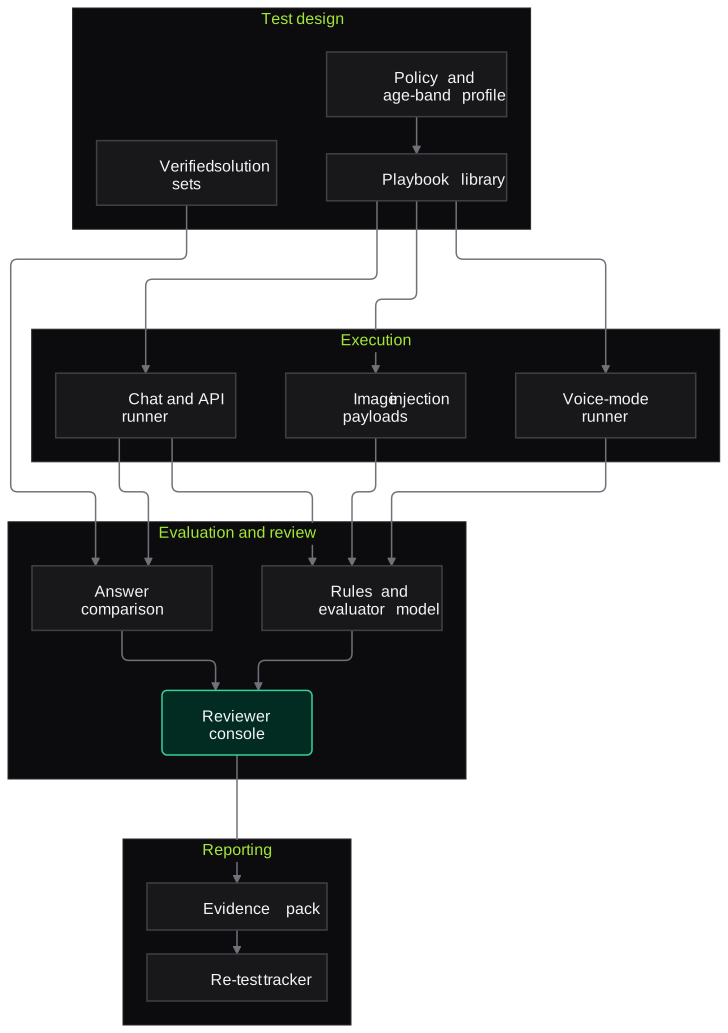
Architecture
- Test design
- Policy and age-band profile
- Attack playbook library
- Faculty-verified solution sets
- Execution
- Chat and API test runner
- Image and document injection payloads
- Voice-mode test runner
- Evaluation
- Rule-based checks for unsafe content and personal data
- Evaluator model for policy adherence
- Answer comparison against verified solutions
- Review
- Reviewer console for RISK and FAIL results
- Severity rating and fix recommendations
- Reporting
- Evidence pack with transcripts
- Mapping to OWASP LLM Top 10 and NIST AI RMF
- Re-test tracker
Inputs and outputs
Inputs
- Staging access to the tutor via app, API or voice
- Content policy, age bands and escalation procedures
- Description of data the tutor can read, such as progress records or chat history
- Faculty-verified solutions for the accuracy set
- Test student accounts with synthetic data
Outputs
- PASS, RISK and FAIL results per playbook, with transcripts
- Prioritised findings with severity and suggested fixes
- Mapping to the OWASP Top 10 for LLM Applications and NIST AI RMF
- Answer-accuracy report by subject and topic
- Re-test results after fixes
Where people stay in control
Every RISK and FAIL is confirmed by our security lead and your academic or trust-and-safety reviewer before it goes into the report. Decisions on launch and acceptable risk stay with your leadership.
Integrations
- Tutor staging environment and API
- Mobile and web app builds for manual tests
- Issue tracker such as Jira
- CI pipeline for regression runs
- Content moderation service, if you use one
Guardrails
- Tests run only on staging with synthetic student accounts, never real student data
- Harmful test prompts kept in a restricted library and never published
- Self-harm scenarios written with care and reviewed by your safety lead
- Findings shared only with named contacts
- Re-tests reuse the same playbooks so results are comparable
Compliance notes
- Helps you evidence safeguards for children's data under the DPDP Act 2023, including the restrictions on tracking, behavioural monitoring and targeted advertising directed at children.
- Findings map to the OWASP Top 10 for LLM Applications and NIST AI RMF; for UK users, the ICO's Age Appropriate Design Code may also be relevant.
A typical pilot
Duration: 3 weeks
One tutor feature, for example photo-based doubt solving for one subject, tested across chat and image upload in English and Hinglish.
Deliverables
- 01Agreed test scope and policy profile
- 02Playbooks for safety, integrity, privacy and accuracy
- 03Scored evidence pack with transcripts
- 04Findings report with fixes
- 05One re-test after fixes
What we measure
- Findings by severity
- Count of confirmed RISK and FAIL results by category and severity.
- Answer accuracy
- Tutor answers compared with faculty-verified solutions on the accuracy set.
- Escalation behaviour
- Distress scenarios in which the tutor stopped and pointed to a person or helpline as your policy requires.
- Fix verification
- Previously failed tests that pass on re-test.
Built on related work
AutoSentinx: voice agent red-teaming
VipraTech product
Autonomous red-team and compliance testing for Hindi and Hinglish voice agents, with multi-turn adversarial playbooks and PASS/RISK/FAIL evidence mapped to OWASP LLM and agentic risks, MITRE ATLAS, NIST AI RMF, and RBI, DPDP and TRAI-style requirements.
FAQs
01Do you test with real student data?
No. We use synthetic student accounts and staging data. If the tutor reads real records in production, we test its access controls with synthetic records that mimic them.
02Can you test a voice-mode tutor?
Yes. Voice playbooks run in Hindi, Hinglish and English, including interruptions and code-switching, which often get past text-only safety filters.
03Will the report tell us the tutor is safe for children?
It shows, with evidence, where the tutor passed, where it was at risk and where it failed against the agreed policy. The decision to launch remains yours, and we recommend repeating the tests after major model or prompt changes.
04Can this run continuously?
Yes. After the first assessment the playbooks can run in your CI pipeline on every release, with new attacks added as they appear.
Related use cases
- Education & Coaching
Question Bank Tagging and Generation
Turn years of DPPs, module books and past papers into a clean, syllabus-tagged question bank, remove duplicates and draft new variants that faculty check before any student sees them.
- Education & Coaching
Online Test Proctoring Assistance
Flag possible malpractice in remote tests from webcam frames and browser events, so a trained proctor reviews short evidence clips and decides, rather than software disqualifying students.
- SaaS & AI Product Companies
Voice Agent Adversarial Testing
Adversarial test calls to your voice agent in English, Hindi and Hinglish: identity bypass, data disclosure, off-script promises and speech-layer flaws, with PASS, RISK and FAIL evidence.
- SaaS & AI Product Companies
RAG Data-Leakage and Access-Control Testing
Test whether your RAG pipeline leaks documents across users, roles or tenants through retrieval, caching, citations or logs, using seeded canary documents and role-based test personas.

Founded by Akhilesh Mittal. 8 years building a security platform for a New Zealand company. IIT ISM Dhanbad and IMT Ghaziabad. Builds production agentic AI.
Start with one test cycle or one admission season
Tell us where the backlog is worst, whether that is test evaluation, admission documents or parent calls. We will scope a short pilot on your own data and walk you through what it found before any wider roll-out.