Red-Teaming for Bank Chatbots and Voice Agents
Adversarial testing of bank chatbots and voice agents for prompt injection, data leakage, account-takeover social engineering and unsafe advice, in English, Hindi and Hinglish.
- Industry:
- Banking
Who it is for
- Chief Information Security Officer
- Head of Digital Banking
- Head of AI and Data Science
- IT Risk and Assurance Manager
The problem
Banks are putting language models behind WhatsApp bots, website assistants and voice agents, often built by a vendor and connected to account APIs. Traditional application penetration tests do not exercise how these systems respond to manipulative conversation, and the attack surface now includes everything a customer, or an attacker posing as one, can say.
Conversation as an attack path
Prompt injection and jailbreaks can make an assistant ignore its instructions, reveal its system prompt or call tools it should not.
Account takeover through social engineering
Attackers test whether a bot will change a registered mobile number, reveal balances or skip verification when pressured or confused.
Hinglish and voice-specific gaps
Guardrails tuned on English text often fail on code-mixed Hindi, transliteration or spoken input with background voices.
No evidence for the risk committee
Vendors say their bot is safe, but the bank lacks independent, repeatable evidence to show its risk committee and auditors.
What we build
We run a structured red-team engagement against your chatbot or voice agent in a test environment you control. Supervised AI attacker agents and human testers work through multi-turn playbooks covering prompt injection, indirect injection through documents or web content, system prompt and data leakage, tool and API misuse, authentication bypass, unsafe financial advice and mis-selling. For voice agents, attacks are delivered as audio, including code-mixed speech, interruptions and background voices. Each finding records the full conversation, its impact and a PASS, RISK or FAIL verdict mapped to the OWASP Top 10 for LLM Applications, MITRE ATLAS and relevant RBI and DPDP expectations. We retest after fixes.
- Multi-turn adversarial playbooks in English, Hindi and Hinglish, with regional languages on request
- Tests for prompt injection, jailbreaks, system prompt leakage and cross-customer data exposure
- Authentication bypass and social engineering scenarios against account-linked tools
- Voice attacks delivered as audio, including barge-in, background speech and false context
- Checks for unsafe investment, loan or tax advice and mis-selling of third-party products
- Evidence pack with transcripts, recordings, verdicts and framework mappings, plus retest
How it works
- 01Agree scope and rulesWe confirm the bot, channels, tools and test accounts in scope, and the rules of engagement with your security team.
- 02Map the attack surfaceWe document the bot's tools, data sources, authentication steps and guardrails from configuration and probing.
- 03Run adversarial playbooksAttacker agents and human testers run multi-turn attacks by text and voice against the test environment.
- 04Validate findingsEvery candidate finding is reproduced and checked by a human tester before it is recorded.
- 05Report with evidenceFindings carry transcripts, recordings, impact, verdicts and framework mappings, with remediation guidance.
- 06Retest fixesAfter your team or vendor fixes issues, we rerun the affected playbooks and update the evidence pack.

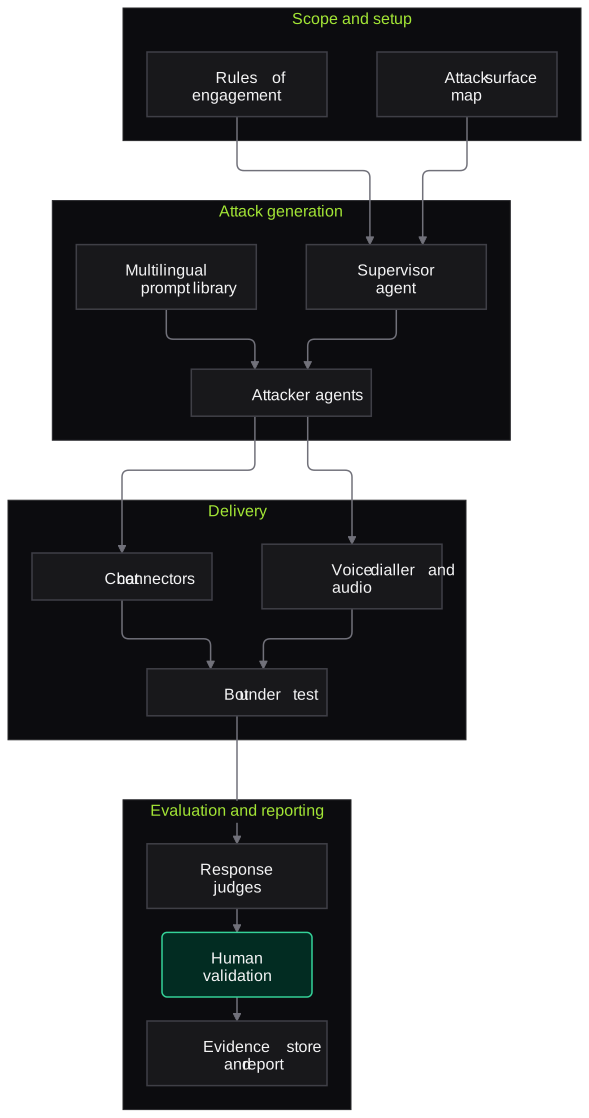
Architecture
- Scope and setup
- Rules of engagement and test accounts
- Attack-surface map of tools and data sources
- Attack generation
- Supervisor agent selecting playbooks
- Attacker agents for text and voice
- Multilingual and code-mixed prompt library
- Delivery
- Chat connectors for web and WhatsApp test numbers
- Audio synthesis and telephony dialler for voice agents
- Evaluation
- Response judges for leakage, policy and tool misuse
- Human validation of each finding
- Mapping to OWASP LLM Top 10, MITRE ATLAS and NIST AI RMF
- Reporting
- Evidence store with transcripts and recordings
- Findings report and retest tracker
Inputs and outputs
Inputs
- Access to the chatbot or voice agent in a test or staging environment
- Test customer accounts and synthetic data
- Bot configuration, tool list and guardrail documentation where available
- Bank policies on authentication, advice and disclosures
- Rules of engagement agreed with the CISO's team
Outputs
- Findings report with PASS, RISK and FAIL verdicts
- Full transcripts and audio recordings for every finding
- Mapping to OWASP LLM Top 10, MITRE ATLAS, NIST AI RMF and FREE-AI themes
- Prioritised remediation guidance for the bank or its vendor
- Retest results and an updated evidence pack
Where people stay in control
Human testers validate every finding before it enters the report, and the bank's security team approves scope and any test that touches live channels. Verdicts come with evidence so your risk committee can make its own judgement.
Integrations
- Chatbot or voice agent test endpoints: web, WhatsApp test number, SIP or phone number
- Bank test environment with synthetic customer data
- Vulnerability management or GRC tool for findings
- Issue tracker used by the bot vendor
- CI pipeline for scheduled regression runs, if required
Guardrails
- Testing only in agreed environments with test accounts; no real customer data
- Transactional or destructive tests only with explicit written approval
- Attack prompts and recordings stored encrypted and shared on a need-to-know basis
- Every finding reproduced before reporting
- Agreed stop conditions if testing affects availability
Compliance notes
- Findings are mapped to the OWASP Top 10 for LLM Applications, NIST AI RMF and themes in RBI's FREE-AI framework, to help the bank evidence AI risk testing.
- Helps evidence safeguards for personal data under the DPDP Act 2023; the report does not certify compliance.
A typical pilot
Duration: 3 weeks
One customer-facing assistant, such as a WhatsApp banking bot, tested in English and Hinglish against a focused set of playbooks for data leakage, authentication bypass and unsafe advice.
Deliverables
- 01Rules of engagement and attack-surface map
- 02Executed playbooks with full transcripts
- 03Findings report with verdicts and framework mappings
- 04Remediation walkthrough with your team or vendor
- 05Retest of fixed findings
What we measure
- Findings by severity and category
- Validated findings per OWASP LLM category and severity, each with reproduction steps.
- Playbook coverage
- Attack scenarios executed against those agreed in scope, by language and channel.
- Behaviour consistency across languages
- The same attack run in English, Hindi and Hinglish, comparing the bot's responses.
- Fix verification
- Findings confirmed fixed on retest, compared with those still reproducible.
Built on related work
LLM endpoint security scanner
Security platform (anonymised)
Workflow that scans Azure-hosted and custom HTTP LLM endpoints for prompt injection, jailbreaks and data leakage.
FAQs
01How is this different from a normal penetration test?
A web or API penetration test checks the application and infrastructure. This engagement tests how the language model behaves in conversation and what it can be manipulated into doing with its tools and data. Many banks need both.
02Do you test in production?
We prefer a staging environment with test accounts. If a production test is needed, it runs with test accounts, agreed time windows and stop conditions approved by your CISO.
03Can you test a vendor's bot?
Yes, with the vendor's cooperation for access and fixes. The report gives the bank independent evidence and gives the vendor reproducible cases to fix.
04Can testing be repeated after each release?
Yes. Playbooks are kept as a regression suite, and we can rerun them on a schedule or after each change to the model, prompts or tools.
Related use cases
- Banking
AI Governance Evidence Pack for Banks
Inventory the bank's AI and ML systems and assemble the evidence boards, auditors and supervisors ask for: purpose, data, testing, monitoring, incidents and accountable owners.
- Banking
Multilingual Voice Agent for Banking Service Requests
An inbound voice agent that authenticates callers and handles card blocking, statements, cheque books and status queries in Hindi, Hinglish and regional languages, with clean handover.
- NBFCs & Lending
Conduct Testing for Collections Voice Agents
Test collections voice agents, in-house or vendor-built, for harassment, third-party disclosure, misrepresentation and vulnerable-borrower handling in Hindi and Hinglish, with audio evidence.
- SaaS & AI Product Companies
LLM Application Penetration Test (OWASP LLM Top 10)
A scoped pentest of your LLM feature and the app around it: prompt injection, data disclosure, output handling, excessive agency and system-prompt leakage, with reproducible evidence.

Founded by Akhilesh Mittal. 8 years building a security platform for a New Zealand company. IIT ISM Dhanbad and IMT Ghaziabad. Builds production agentic AI.
Pick one banking process and test it with evidence
Book a discovery call to choose a narrow pilot, from KYC file checks to voice-agent red-teaming, and see measured results on your own documents before any wider roll-out.