AI Assurance and Red-Teaming Delivery for Advisory Firms
A white-label technical partner for advisory firms: we run adversarial tests on clients' chatbots, voice agents and copilots and deliver framework-mapped evidence for your report.
- Capability:
- AI Security & Compliance
- Industry:
- Accounting, Audit & Consulting
Who it is for
- Partner, Risk Advisory
- Director, Technology Risk and IT Audit
- AI Governance Practice Lead
- Cyber Security Consulting Manager
The problem
Banks, insurers and product companies are asking their auditors and consultants for assurance over the AI systems they have shipped: chatbots, voice agents, internal copilots and agents that call tools. Advisory firms have the governance frameworks and the client relationships, but adversarial testing of an LLM application is specialised engineering work that few risk teams have staffed for.
Demand outpaces skills
Governance reviewers can assess policies and controls but are not equipped to run prompt injection or multi-turn jailbreak campaigns.
Checklists do not test behaviour
A policy review shows that a control exists, not that the bot actually resists a determined user over a long conversation.
Evidence must map to frameworks
Clients expect findings tied to OWASP Top 10 for LLM Applications, NIST AI RMF, ISO/IEC 42001, the EU AI Act or RBI's FREE-AI framework.
Hiring for uncertain demand is risky
Building an in-house red team before the pipeline is steady leaves expensive specialists under-used.
What we build
We work as the technical delivery team behind your AI assurance engagements, under your brand and engagement terms. Your team scopes the work with the client and owns the conclusion; we run the testing. For each system in scope, whether a support chatbot, a Hindi or Hinglish voice agent, a RAG copilot or an agent with tool access, we build adversarial test plans covering prompt injection, jailbreaks, data leakage, unauthorised tool use, harmful advice and sector-specific conduct failures. Tests run as repeatable multi-turn playbooks, and each result is recorded as PASS, RISK or FAIL with transcripts, mapped to the frameworks your report uses, and handed over as a working-paper-ready evidence pack.
- Test planning aligned to your engagement scope and the client's AI risk register
- Multi-turn adversarial playbooks for chatbots, voice agents, RAG copilots and tool-using agents
- Sector conduct tests such as mis-selling, collection conduct or unauthorised investment advice
- PASS, RISK and FAIL results with full transcripts or call audio, reproducible on retest
- Mapping to OWASP Top 10 for LLM Applications, MITRE ATLAS, NIST AI RMF, ISO/IEC 42001 and EU AI Act duties
- Evidence packs and draft technical findings in your report template, plus retests after remediation
How it works
- 01Scope with the advisory teamWe agree systems, access, test windows and rules of engagement with your engagement manager and the client.
- 02Build the test planAdversarial playbooks are selected and adapted to the client's sector, languages and risk register.
- 03Run the testsPlaybooks run against the client's system in the agreed environment, with every turn recorded.
- 04Classify and verify resultsEach result is scored PASS, RISK or FAIL, and borderline results are reviewed jointly with your manager.
- 05Map evidenceVerified results are mapped to the frameworks in your report and assembled into an evidence pack.
- 06Report and retestYour firm issues the report, and we retest fixed issues after the client's remediation.

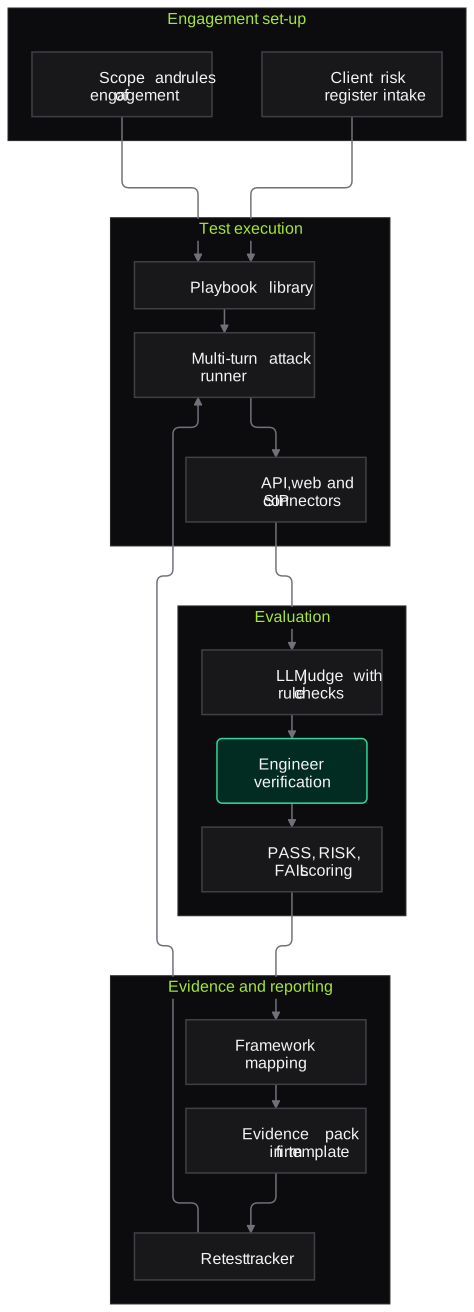
Architecture
- Engagement set-up
- Scope and rules of engagement
- Test environment access
- Client risk register intake
- Test execution
- Adversarial playbook library
- Multi-turn attack runner for text and voice
- API, web widget and SIP connectors
- Evaluation
- LLM-assisted judge with rule checks
- Engineer verification of every RISK and FAIL
- Transcript and audio capture
- Evidence and reporting
- Framework mapping
- Evidence pack in the advisory firm's template
- Retest tracker
Inputs and outputs
Inputs
- Engagement scope and rules of engagement
- Access to the system under test in a test or staging environment
- System prompts, policies and tool definitions where the client shares them
- Client AI risk register and applicable regulations
- Your firm's report template and framework mapping
Outputs
- Test plan and coverage matrix
- PASS, RISK and FAIL results log with transcripts and audio
- Framework-mapped evidence pack
- Draft technical findings with remediation suggestions
- Retest results after remediation
Where people stay in control
A VipraTech engineer verifies every RISK and FAIL result before it enters the evidence pack, and borderline results are reviewed jointly with your engagement manager. Your partners decide severity in the final report and issue the conclusion; we provide the technical evidence.
Integrations
- Client chatbot APIs or web widgets
- Telephony or SIP endpoints for voice agents
- LLM platforms such as Azure OpenAI, AWS Bedrock or Google Vertex AI
- Your working paper or GRC tool
- Jira or similar for remediation tracking
Guardrails
- Written rules of engagement and test windows approved by the client
- Synthetic test data only, never real customer personal data
- Tool-using agents tested with sandboxed or non-destructive actions
- White-label confidentiality under your NDA and engagement terms
- Evidence stored in your environment or transferred encrypted to named contacts
Compliance notes
- Evidence is mapped to frameworks such as NIST AI RMF, ISO/IEC 42001 and the OWASP Top 10 for LLM Applications to help your team evidence its conclusions; it is not a certification.
- For Indian financial-sector clients, tests can reflect RBI's FREE-AI framework (2025) recommendations and DPDP Act 2023 obligations; EU AI Act duties are considered where the client serves the EU.
A typical pilot
Duration: 4 weeks
One client system, such as a customer-facing chatbot or voice agent, on a joint engagement with a fixed playbook set and one retest.
Deliverables
- 01Joint delivery model and rules-of-engagement template
- 02Test plan and coverage matrix for the pilot system
- 03Verified results log and evidence pack in your template
- 04Draft technical findings
- 05Retest report
What we measure
- Coverage against scope
- Scenarios executed per agreed risk category, recorded in the coverage matrix.
- Verified findings
- RISK and FAIL results confirmed after engineer and joint review.
- Retest closure
- Findings shown as fixed when the same playbooks are re-run after remediation.
- Report integration effort
- Time your team spends adapting our evidence into the final report.
Built on related work
AutoSentinx: voice agent red-teaming
VipraTech product
Autonomous red-team and compliance testing for Hindi and Hinglish voice agents, with multi-turn adversarial playbooks and PASS/RISK/FAIL evidence mapped to OWASP LLM and agentic risks, MITRE ATLAS, NIST AI RMF, and RBI, DPDP and TRAI-style requirements.
FAQs
01Do you work under our brand?
Yes. We deliver as your technical team under your engagement terms and NDA, and reports go out under your name. We join client calls only if you want us there, and we do not contact your clients directly.
02What kinds of AI systems can you test?
Text chatbots, Hindi, Hinglish and English voice agents reached by phone or SIP, RAG copilots over internal documents, and agents that call tools or APIs. We agree the systems and access method during scoping.
03Do you certify the client's AI system?
No. We provide technical test evidence mapped to the frameworks you choose. Your firm forms the assurance conclusion, and neither of us presents the work as a certification.
04How are engagements priced?
Usually as a fixed fee per system tested, based on scope and the number of playbooks, with retests priced separately. A first joint engagement can run as a pilot to agree the working model.
Related use cases
- Banking
Red-Teaming for Bank Chatbots and Voice Agents
Adversarial testing of bank chatbots and voice agents for prompt injection, data leakage, account-takeover social engineering and unsafe advice, in English, Hindi and Hinglish.
- Banking
AI Governance Evidence Pack for Banks
Inventory the bank's AI and ML systems and assemble the evidence boards, auditors and supervisors ask for: purpose, data, testing, monitoring, incidents and accountable owners.
- SaaS & AI Product Companies
LLM Application Penetration Test (OWASP LLM Top 10)
A scoped pentest of your LLM feature and the app around it: prompt injection, data disclosure, output handling, excessive agency and system-prompt leakage, with reproducible evidence.
- SaaS & AI Product Companies
EU AI Act and ISO/IEC 42001 Evidence Pack
Assemble testing records, risk assessments, oversight design and technical documentation for your AI features, mapped to EU AI Act and ISO/IEC 42001 requirements, ready for counsel and auditors.

Founded by Akhilesh Mittal. 8 years building a security platform for a New Zealand company. IIT ISM Dhanbad and IMT Ghaziabad. Builds production agentic AI.
Start with one engagement
Pick one reconciliation, one audit area or one tax-season workflow. We will scope a short pilot on your own documents and show the results against work your team has already done.