Guardrail Testing for AI Shopping Assistants
Adversarial testing of AI shopping assistants for unauthorised discounts, wrong prices, order-data leakage and unsafe product advice, with validated findings, fixes and a retest.
- Capability:
- AI Security & Compliance
- Industry:
- Retail, D2C & Quick Commerce
Who it is for
- Head of E-commerce Product
- CTO or Head of Engineering
- CISO
- Head of Customer Experience
The problem
Retailers are putting AI assistants on their sites, apps and WhatsApp channels to answer product questions, track orders and apply offers. An assistant that can look up orders or apply coupons can also be talked into doing the wrong thing, and a wrong price stated by your bot is a customer complaint in writing.
Talked into discounts
Users try role-play and persistence to get coupons, price matches or free shipping the business never approved.
Order tools that leak data
An order lookup tool without proper checks can reveal another customer's address or phone number.
Hallucinated prices and policies
The assistant states a price, stock position or return policy that is not true, and screenshots spread.
Injection through product content
Reviews, seller descriptions and Q&A that the assistant reads can carry instructions that change its behaviour.
What we build
We test your shopping assistant the way a determined customer, a fraudster or a competitor would. We map its knowledge sources, tools and permissions, then run automated adversarial suites and manual sessions in English, Hindi and Hinglish. Tests cover prompt injection, indirect injection through reviews and catalogue text, coupon and price manipulation, cross-customer data access through order tools, system prompt and margin disclosure, unsafe advice on supplements, cosmetics or baby products, and brand-damaging output. Every finding is reproduced by an engineer, rated and mapped to the OWASP Top 10 for LLM Applications. We retest after fixes and hand over a regression pack.
- Coupon, discount and price-manipulation tests against your actual offer rules
- Cross-customer data access tests on order lookup, returns and address tools
- Direct and indirect prompt injection, including payloads planted in reviews and product Q&A
- Hallucination checks on prices, stock, delivery promises and return policy
- Unsafe-advice and brand-safety tests for sensitive categories in English, Hindi and Hinglish
- Validated findings mapped to OWASP LLM Top 10, with a regression pack for CI
How it works
- 01Agree scopeWe agree the assistant, channels, test accounts, staging environment and what is off limits.
- 02Map sources and toolsCatalogue, policy and review sources, plus order, coupon and returns tools, are mapped with their permissions.
- 03Run adversarial testsAutomated suites and manual testers attack the assistant across every mapped risk and language.
- 04Validate findingsEngineers reproduce each candidate issue and drop anything they cannot confirm.
- 05Report and fixYou receive validated findings with evidence, severity and recommended fixes.
- 06Retest and hand overFixes are retested, and the test cases become a regression pack for future releases.

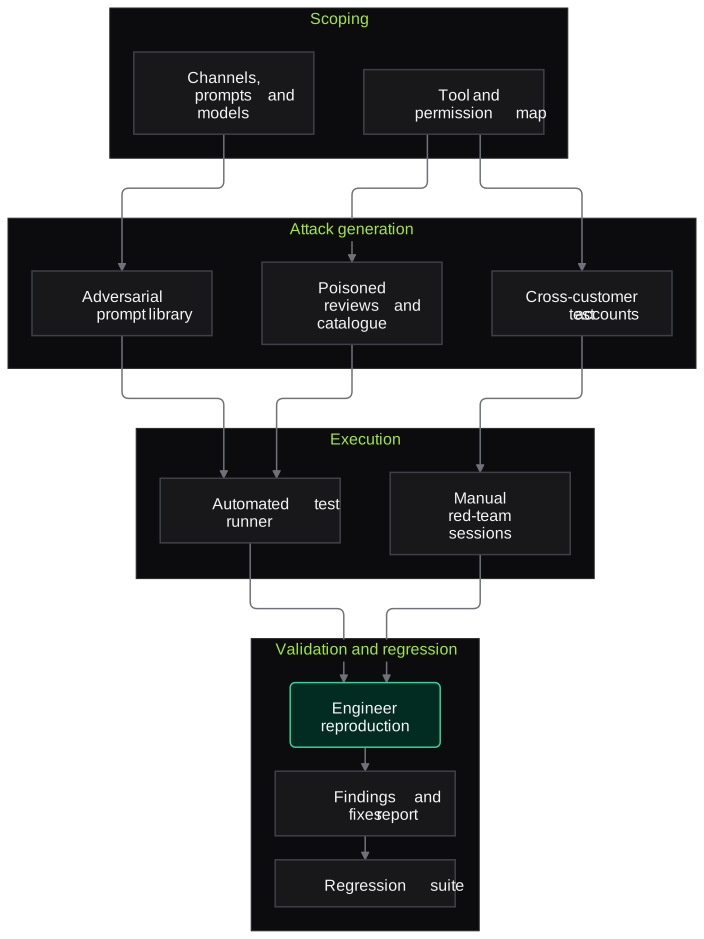
Architecture
- Scoping
- Assistant inventory of channels, prompts and models
- Tool and permission map
- Offer and policy rules used as test oracles
- Attack generation
- Adversarial prompt library in English, Hindi and Hinglish
- Poisoned review and catalogue content set
- Cross-customer test accounts
- Execution
- Automated test runner for web, app and WhatsApp channels
- Manual red-team sessions
- Conversation and tool-call capture
- Validation and reporting
- Engineer reproduction and severity rating
- OWASP LLM Top 10 mapping and fix guidance
- Regression
- Retest of fixed findings
- Regression suite for CI
Inputs and outputs
Inputs
- Access to the assistant in staging on web, app or WhatsApp
- System prompts, tool definitions and model configuration
- Offer, coupon and return policy rules
- Test customer accounts with seeded orders
- Sample catalogue, review and Q&A content
Outputs
- Threat model and test plan
- Validated findings with severity, transcripts and reproduction steps
- Mapping to OWASP LLM Top 10
- Fix guidance for prompts, tools, retrieval and output filters
- Retest results and regression pack
Where people stay in control
Our engineers reproduce every automated finding before it reaches the report. Your product, legal and CX owners decide how each risk is treated, and tests run only against staging with test accounts.
Integrations
- Assistant platform or custom LLM application
- Order, coupon and returns APIs in staging
- WhatsApp Business API test number
- Issue tracker such as Jira
- CI pipeline for regression tests
Guardrails
- Tests use seeded test accounts, never real customer data
- No coupons redeemed or orders placed in production
- Testing only within agreed scope and time windows
- Transcripts and findings stored encrypted with restricted access
Compliance notes
- Wrong prices or policies stated by an assistant can raise issues under the Consumer Protection Act 2019 and E-Commerce Rules 2020; testing helps you find them before customers do.
- Exposure of customer data through order tools is a personal data breach risk under the DPDP Act 2023.
- For EU customers, the EU AI Act includes transparency obligations so that people know when they are interacting with an AI system.
A typical pilot
Duration: 2 to 3 weeks
One assistant on one channel, such as website chat or a WhatsApp bot, in staging with its order and coupon tools.
Deliverables
- 01Rules of engagement and threat model
- 02Executed test plan with transcripts
- 03Validated findings report with fix guidance
- 04Read-out with product and engineering
- 05Retest and regression pack
What we measure
- Test coverage
- Test cases run per OWASP LLM category, tool and language.
- Validated findings by severity
- Engineer-confirmed findings at each severity level.
- Policy deviation rate
- Share of test conversations where the assistant stated a price, offer or policy that contradicts your rules.
- Fix verification
- Pass or fail status of each finding on retest.
FAQs
01We use a vendor's chatbot platform. Can you still test it?
Yes. We test the assistant as deployed for you, including your prompts, knowledge sources and connected tools. Issues in the platform itself are reported so you can raise them with the vendor.
02Do you test in Hindi and Hinglish?
Yes. Guardrails that hold in English often fail in Hindi, Hinglish or transliterated text, so our attack library covers all three.
03Will testing affect real customers or orders?
No. Tests run in staging with seeded accounts, and no coupons are redeemed or orders placed in production.
04How often should we retest?
After any change to the model, prompts, tools or offer logic, and before major sale events. The regression pack lets your team run the core tests in CI between full reviews.
Related use cases
- Retail, D2C & Quick Commerce
Catalogue Enrichment from Product Images
Read product photos and back-of-pack images to fill category attributes, mandatory declarations and listing copy for each marketplace, with every value checked before publishing.
- Retail, D2C & Quick Commerce
Order Status and Returns Voice Agent
A multilingual voice agent that answers where-is-my-order calls from live courier data, starts returns and exchanges under your policy, and hands disputes to an agent with context.
- SaaS & AI Product Companies
LLM Application Penetration Test (OWASP LLM Top 10)
A scoped pentest of your LLM feature and the app around it: prompt injection, data disclosure, output handling, excessive agency and system-prompt leakage, with reproducible evidence.
- SaaS & AI Product Companies
RAG Data-Leakage and Access-Control Testing
Test whether your RAG pipeline leaks documents across users, roles or tenants through retrieval, caching, citations or logs, using seeded canary documents and role-based test personas.

Founded by Akhilesh Mittal. 8 years building a security platform for a New Zealand company. IIT ISM Dhanbad and IMT Ghaziabad. Builds production agentic AI.
Pick one leak and measure it
Book a discovery call. We will choose one narrow pilot, such as COD confirmation, one claim type or one dark store, run it alongside your current process and report what we measured.