Guardrail Testing for Investment Advisory Chatbots
Test wealth and broking chatbots for unregistered advice, missing risk disclosures, made-up fund data, prompt injection and client data leakage, scored against your SEBI registration scope.
- Capability:
- AI Security & Compliance
- Industry:
- Capital Markets & Wealth Management
Who it is for
- Chief Compliance Officer
- Head of Digital Wealth
- Chief Information Security Officer
- Principal Officer, Investment Adviser
The problem
Brokers, mutual fund distributors, wealth platforms and registered advisers are adding chatbots that explain funds, summarise portfolios and answer market questions. What the bot may say depends on the firm's registration: a distributor or execution-only broker must not give personalised advice, and a registered adviser must keep advice within suitability and disclosure rules.
Information slides into advice
A helpful answer about a fund can become a personalised recommendation after a few follow-up questions.
Wrong numbers sound confident
Language models can state NAVs, returns or expense ratios that are outdated or invented.
Missing risk language
Required risk disclosures and past-performance caveats disappear in shorter or multi-turn answers.
Data and injection risks
Bots that read portfolios or notes can be manipulated by injected instructions or tricked into revealing another client's holdings.
What we build
We test your chatbot against a rubric built for your registration type and permitted scope. Scenarios cover advice boundaries, suitability behaviour if you are a registered adviser, mandatory risk disclosures, assured-return and tip-seeking prompts, factual accuracy against reference data such as scheme NAVs and expense ratios, prompt injection and cross-client data leakage. We run multi-turn conversations in English and Hinglish with personas such as a retiree with a lump sum, a derivatives trader asking for tips and a user pasting instructions into a portfolio note. Each conversation is scored PASS, RISK or FAIL, with transcripts as evidence, remediation advice and a regression suite.
- Builds a rubric from your registration type, permitted scope, disclosure rules and prohibited claims
- Runs multi-turn adversarial scenarios on advice boundaries, tips, assured returns and suitability
- Checks factual answers on NAVs, returns and expense ratios against reference data
- Tests prompt injection through user messages, uploaded documents and portfolio notes
- Tests isolation between client accounts using synthetic portfolios
- Delivers PASS, RISK and FAIL findings with transcripts, OWASP LLM Top 10 mapping and a regression suite
How it works
- 01Scope and rubricRegistration type, permitted scope, bot features and the scoring rubric are agreed with compliance.
- 02Build scenarios and reference dataPersonas, attack variations and reference answers are prepared from scheme documents and public data.
- 03Run testsMulti-turn conversations are run on the staging bot using synthetic client accounts.
- 04Score and adjudicateTranscripts are scored automatically against the rubric, and any RISK or borderline result passes to your compliance or principal officer.
- 05ReportFindings are prioritised with transcripts, root-cause notes and recommended fixes.
- 06Re-test and automateFixes are re-tested, and the scenarios are added to your release pipeline.

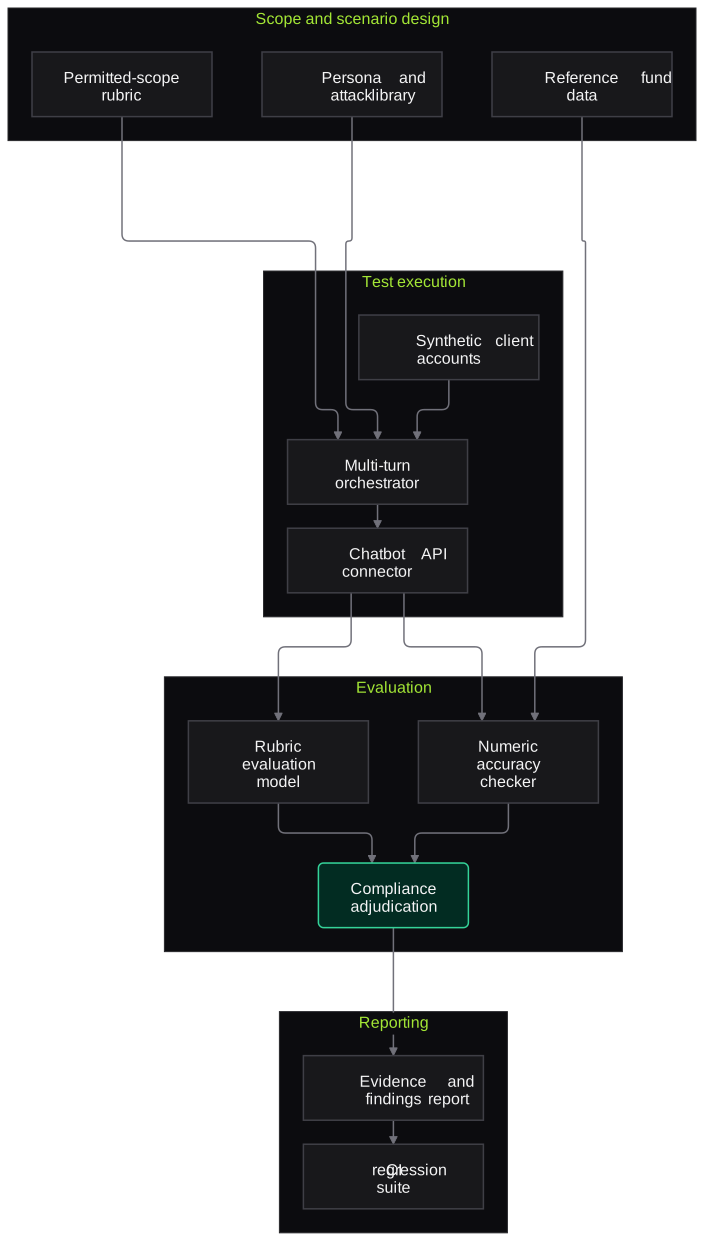
Architecture
- Scope and scenario design
- Registration and permitted-scope rubric
- Persona and attack library
- Reference answers from scheme documents and public NAV data
- Test execution
- Chatbot API connector
- Synthetic client accounts and portfolios
- Multi-turn orchestrator
- Evaluation
- Rubric evaluation model
- Numeric accuracy checker
- Compliance adjudication queue
- Reporting
- Evidence store and findings report with OWASP LLM Top 10 mapping
- CI regression suite
Inputs and outputs
Inputs
- Staging chatbot access and bot documentation
- Registration type and permitted scope
- Scheme documents, factsheets and public NAV data for reference answers
- Approved disclosures and prohibited claims list
- Risk profiling and suitability logic, for registered advisers
- Synthetic test accounts with sample portfolios
Outputs
- Scenario-by-scenario results marked PASS, RISK or FAIL
- Transcripts as evidence
- Factual accuracy report against reference data
- Mapping to the OWASP Top 10 for LLM Applications and internal policies
- Remediation guidance and regression suite
Where people stay in control
Your compliance officer or principal officer signs off the rubric and adjudicates RISK and uncertain results. Product and engineering teams decide on fixes, and we re-test them.
Integrations
- Staging chatbot API or web widget
- Test user accounts in a sandbox
- Reference data such as AMFI NAV files and scheme masters
- CI/CD pipeline
- Jira or a similar issue tracker
Guardrails
- Synthetic accounts only; no real client data
- Testing in staging under a written scope
- Rate-limited test runs
- Findings shared only with named stakeholders
- People check a sample of evaluation model scores
Compliance notes
- The rubric reflects the SEBI distinction between investment advice by registered advisers and distribution or execution services; findings help evidence controls, not obtain approval.
- Aligned with SEBI's position that regulated entities are responsible for the output of AI tools they use, and mapped to the OWASP Top 10 for LLM Applications.
A typical pilot
Duration: 3 weeks
One chatbot journey, such as mutual fund discovery or portfolio summary, tested in English and Hinglish against the agreed rubric.
Deliverables
- 01Rubric approved by compliance, with the scenario list
- 02Executed test run with transcripts
- 03Factual accuracy and findings report
- 04Re-test of agreed fixes
- 05Regression suite
What we measure
- Scenario coverage
- Advice, disclosure, accuracy, injection and isolation categories covered, listed against scope.
- Findings by severity
- FAIL and RISK results per category after compliance adjudication.
- Factual accuracy on reference questions
- Bot answers compared with reference data for NAVs, returns and expense ratios on the test date.
- Evaluator agreement
- Agreement between the evaluation model and compliance reviewers on sampled transcripts.
Built on related work
AutoSentinx: voice agent red-teaming
VipraTech product
Autonomous red-team and compliance testing for Hindi and Hinglish voice agents, with multi-turn adversarial playbooks and PASS/RISK/FAIL evidence mapped to OWASP LLM and agentic risks, MITRE ATLAS, NIST AI RMF, and RBI, DPDP and TRAI-style requirements.
FAQs
01Why does our registration type matter?
Because what counts as a failure differs. A distributor's bot should not give personalised recommendations at all, while a registered adviser's bot may, within suitability and disclosure rules. We build the rubric around your actual scope.
02Do you test against live market data?
We prepare reference answers from scheme documents and public NAV data for the test date, so factual answers can be checked objectively. Live trading systems are not touched.
03Is this a SEBI approval or certification?
No. It is structured evidence of how your bot behaved against defined scenarios, which your compliance team can use in its own control testing and governance records.
04Can you test our voice bot as well?
Yes. The same scenarios can be run as synthetic voice calls in Hindi and English and scored from transcripts and audio.
Related use cases
- Capital Markets & Wealth Management
Data-Leakage Testing for Internal Research Copilots
Test internal research and RM copilots for leakage across information barriers, research entitlements and client data, including prompt injection through ingested documents.
- Capital Markets & Wealth Management
Voice Agent for Trading Support and Account Queries
Inbound voice agent for brokers that verifies clients, answers payout, margin, order-rejection and IPO queries from live data, declines advice and routes order requests to dealers.
- Insurance
Mis-Selling and Disclosure Testing for Insurance Bots
Test insurance sales and service bots for mis-selling, missing disclosures, prompt injection and data leakage, in English, Hindi and Hinglish, with transcript evidence for every finding.
- SaaS & AI Product Companies
LLM Application Penetration Test (OWASP LLM Top 10)
A scoped pentest of your LLM feature and the app around it: prompt injection, data disclosure, output handling, excessive agency and system-prompt leakage, with reproducible evidence.

Founded by Akhilesh Mittal. 8 years building a security platform for a New Zealand company. IIT ISM Dhanbad and IMT Ghaziabad. Builds production agentic AI.
Start with one statement type, queue or chatbot
Book a discovery call and we will scope a short pilot on your de-identified documents or staging systems, with measures agreed before we start.